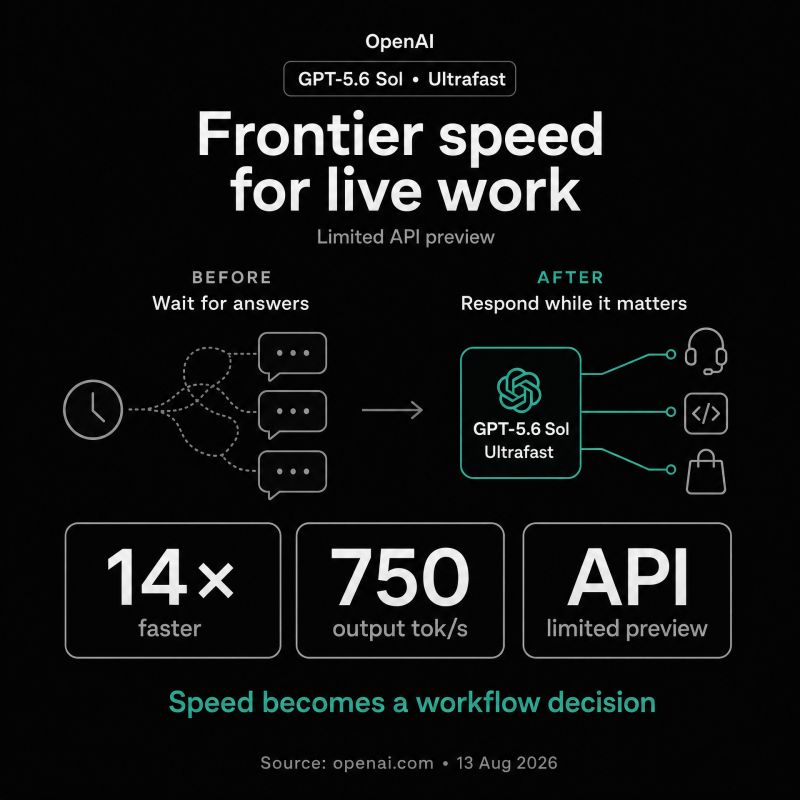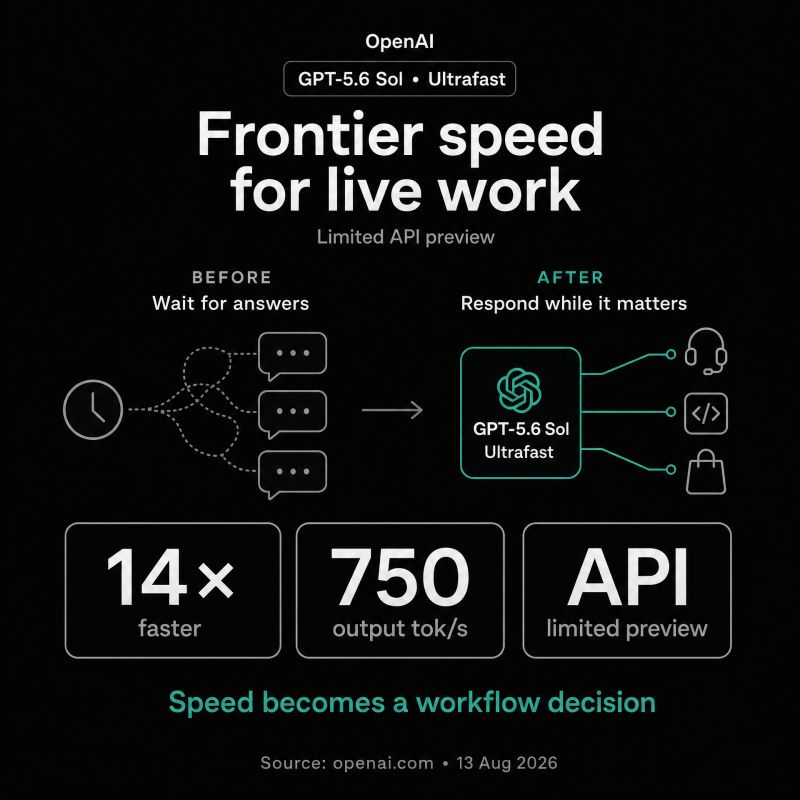
OpenAI just previewed a way to make frontier-model latency a product decision—not a model downgrade. Up to 14× faster. 🧵
In a live support call or a production incident, an answer that arrives after the moment has passed has limited operational value.
Teams have typically cut latency by switching to a smaller or more specialized model. That creates an awkward trade-off: intelligence or responsiveness.
OpenAI’s new Ultrafast API tier runs GPT-5.6 Sol at up to 14× the speed of Standard processing, according to OpenAI. Powered by Cerebras, it is designed to generate up to 750 output tokens per second.
- Up to 14× faster than Standard processing
- Up to 750 output tokens per second
- Built for time-sensitive workflows
- Launches first in the OpenAI API
The interesting part is not “faster chat.” It is tighter human-in-the-loop cycles: read logs, test a hypothesis, ask the next question—while the system is still changing.
My honest take: this is a limited preview, not broad availability, and headline throughput is not the same as end-to-end product latency. But if frontier reasoning can reliably fit inside a live workflow’s response budget, some agent UX assumptions will have to change.
📚 Source: https://lnkd.in/duJGnbnJ
P.S. Where does model latency break your workflow today? 👇