From large scale computers fitting inside the whole room (data-centre-requiring heavy LLMs) 🔜 small, personal devices (consumer-device-fitting LLM).
While we likely won’t see full replacement of data centres - I really hope that a fully capable LLM fitting your iPhone is coming.
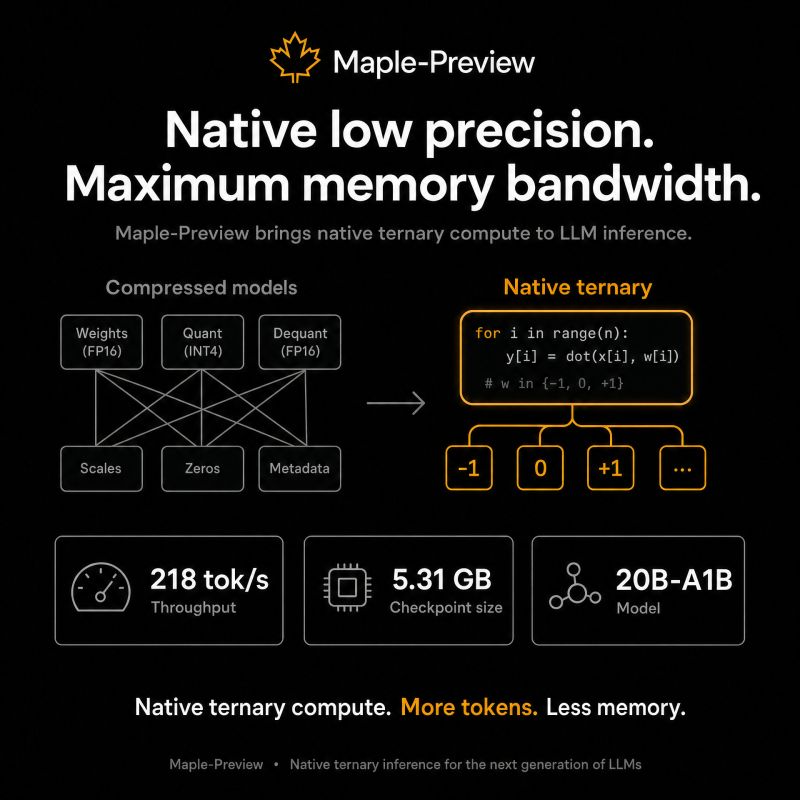
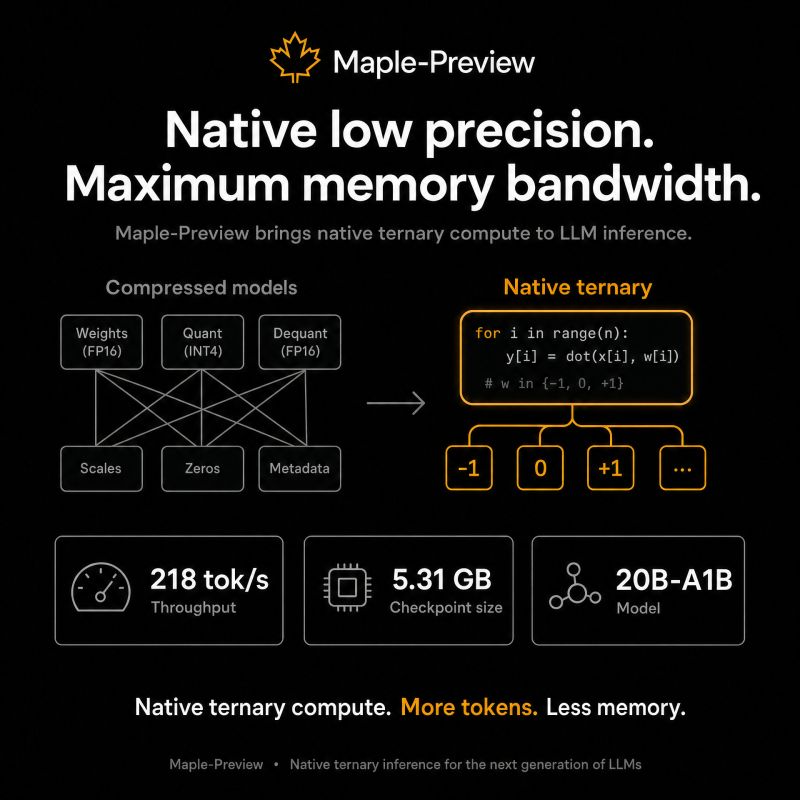
DeepGrove just open-sourced Maple-Preview and reports great results. It’s a 20B-A1B ternary-weight reasoning LLM built natively for low precision from day one.
Instead of compressing a large model, they designed a 24-layer, 256-expert architecture with hybrid sliding-window attention specifically to bound KV-cache growth and maximize memory bandwidth.
While that particular model we can start to compare to only 2024 OpenAI’s results, the direction is clear.
Most “efficient” models start large and get squeezed down to fit local hardware. But when you force a full-precision model into low bitwidths, you hit architectural constraints that limit both performance and efficiency.
Why DeepGrove’s approach works:
- 218 tokens/s decode on a Mac mini
- 5.31 GB checkpoint footprint on disk
- Solves IMO-level problems entirely on-device
- Released under the MIT License
The real breakthrough isn’t just the speed—it’s the hardware-aware design loop. By treating low precision as a first-class citizen during training, Maple avoids the typical trade-offs of post-training quantization.
It’s built for interactive, on-device inference where memory bandwidth is the absolute bottleneck.
My honest take: this is a preview focused on raw reasoning. DeepGrove admits it has had minimal post-training for agentic tasks and only small-scale RL, so it may underperform as an autonomous agent right now. But as a proof-of-concept for native ternary-weight performance, it’s a massive step forward.
📚 Source: https://lnkd.in/dGftuan2
P.S. How much RAM does your current local reasoning model need to run comfortably? 👇